
AI fails the 'cupcake test': Researchers find chatbots can't spot your bad ideas
Original headline: Introducing XYBench: Helping with the problem behind the question — huggingface.co
More in AI and machine learning news
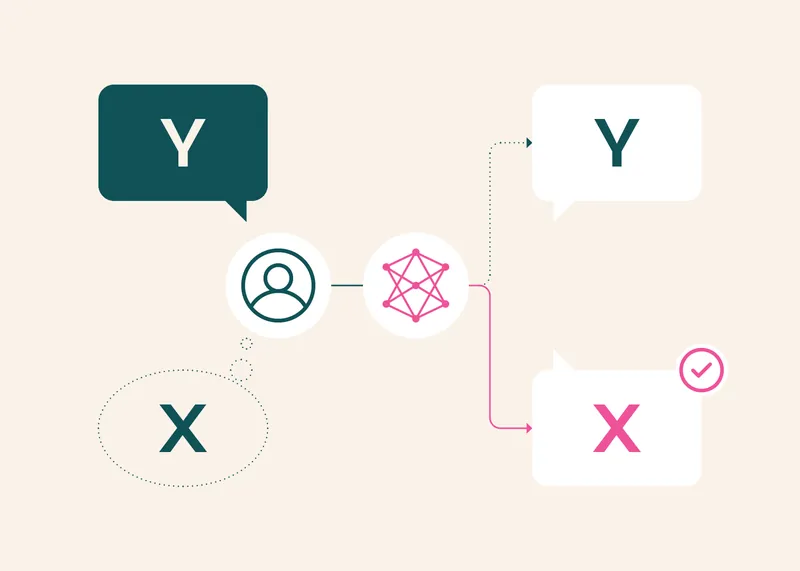
A research team from Carnegie Mellon, NVIDIA, and Johns Hopkins has created a new benchmark called XYBench to test whether AI assistants can identify when users are asking the wrong question. The benchmark includes over 8,000 real-world examples where people describe a faulty solution (like thickening frosting) instead of the actual problem (like warm cupcakes). It specifically measures if AI models can recognize these 'XY problems'—where someone asks about approach Y when they really need solution X—and redirect users accordingly.
When testing top models like Claude Sonnet 4.6, GPT-5, Gemini 3.1 Pro, Qwen3.5-9B, and DeepSeek-V4 Pro, researchers found all five consistently failed this test. Unlike human responses, the AIs would politely answer the misguided question rather than identifying the underlying misconception and suggesting a better approach. This reveals a critical gap in making AI truly helpful for real users who may not know how to properly frame their problems.
Read the original at huggingface.co
Satirical commentary on real tech news, summarised with AI. Read the original source for the facts. How ZeroDaily works