
Google Drops a Speed Bomb for AI Models, Making Big LLMs Feel Suddenly Snappy
Original headline: Google Releases TPU Sync: Open-Source KV Cache Transfer for TPUs — marktechpost.com
More in AI and machine learning news
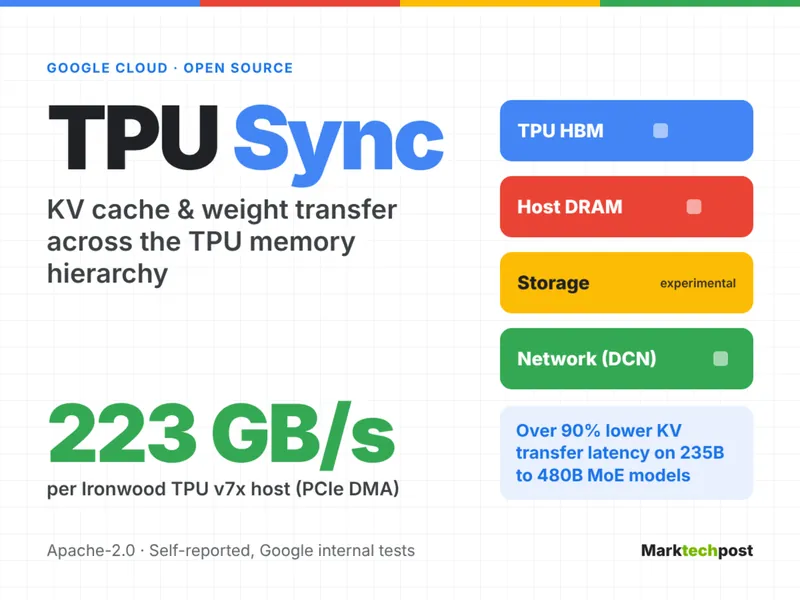
Google has open-sourced TPU Sync, a C++ library designed to tackle a major bottleneck in running massive AI models: moving data around. The library treats the TPU's high-bandwidth memory, the host computer's RAM, shared storage, and the data center network as one unified system, focusing on efficiently shuttling the model's internal state—specifically the 'KV cache'—instead of just crunching numbers. Google claims it can slash the time to transfer this cache by over 90% for behemoth models with hundreds of billions of parameters.
For engineers and users, this means the frustrating wait for a model to start generating text—the 'time to first token'—could drop dramatically. In one example, transferring the cache for a 235-billion-parameter model went from 'several seconds' to a much snappier ~230 milliseconds. While the tech is still early and numbers are from Google's own labs, it's a clear, open-source shot at solving a critical infrastructure problem that defines how fast and responsive our largest AI models can be. The takeaway: Making AI faster isn't just about more FLOPS; it's about moving its memory around with surgical precision.
Read the original at marktechpost.com
Satirical commentary on real tech news, summarised with AI. Read the original source for the facts. How ZeroDaily works