
This API turns messy PDFs into structured data with proof you can trust
Original headline: Nutrient Data Extraction API: JSON Matching Your Schema With Per-Field Citations and Confidence — marktechpost.com
More in AI and machine learning news
Nutrient (formerly PSPDFKit) has launched a document parsing API specifically designed to reduce costly errors from large language models. It extracts structured JSON data from PDFs, images, and Office files, but crucially, it links every extracted data point back to its source with a bounding box, a confidence score, and a citation. This allows developers to verify that the 'nutrients'—the key data points—came from the correct part of the document.
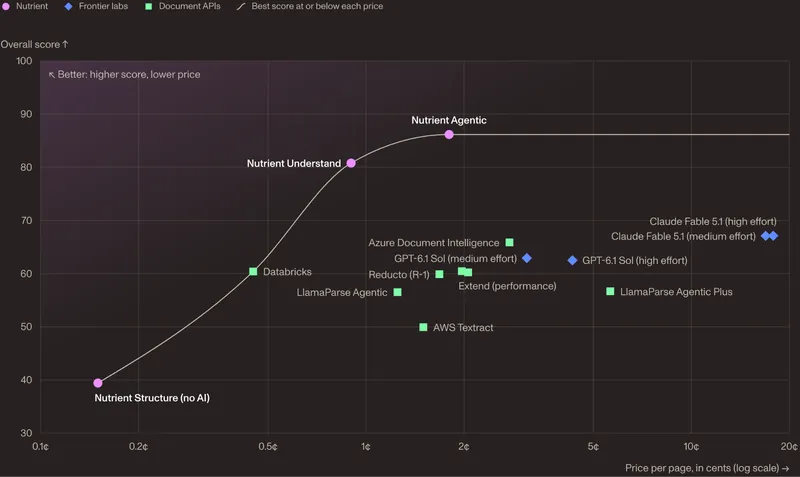
For developers building document pipelines, this addresses the 'black box' problem of AI extraction where you can't audit results. It offers four parsing modes, from simple text extraction to a more expensive 'agentic' mode for degraded scans, with clear performance and cost benchmarks. The takeaway is a practical, auditable tool that brings much-needed transparency to automated document processing, letting you see exactly where your data came from.
Read the original at marktechpost.com
Satirical commentary on real tech news, summarised with AI. Read the original source for the facts. How ZeroDaily works