
New trick makes monster 180B AI models run on a single gaming GPU
Original headline: 180B Parameters, 32GB of RAM: Pushing MoE Inference to the Limit with Transformers — huggingface.co
More in AI and machine learning news
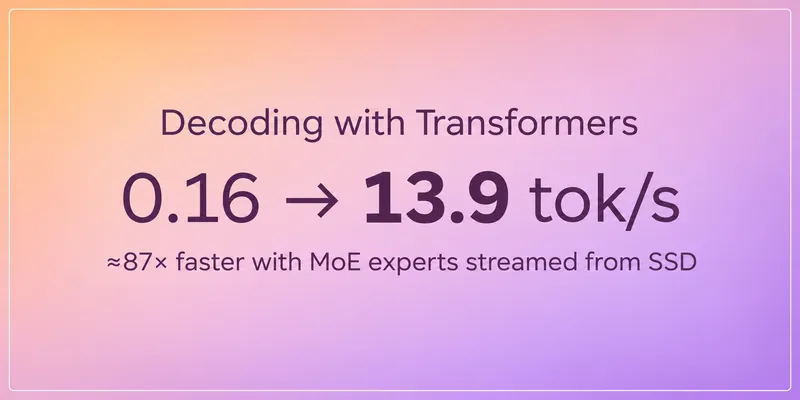
A developer has pushed the limits of running massive Mixture of Experts (MoE) AI models locally, testing a 180-billion-parameter model called Qwen 3.8-Flash-Next on consumer hardware. Using an inference engine called Strata, the technique keeps only the most active 'experts'—the specialized sub-networks that make up over 90% of the model's weight—in the GPU's VRAM, while the rest spill over to system RAM or even an SSD. This allows a model that would normally require hundreds of gigabytes of GPU memory to run on a single RTX 4090 or a MacBook with 32GB of unified memory.
The breakthrough makes frontier-scale AI models accessible to developers and researchers without access to expensive data center-grade hardware. While speeds on a MacBook (around 13.5 tokens per second) are currently too slow for real-time coding assistance, the technique opens the door for local experimentation with models previously thought impossible to run outside the cloud. The author compares Strata's approach to other popular engines like llama.cpp and vLLM, which handle offloading differently, often with trade-offs in speed or memory fragmentation. This is a significant step towards democratizing powerful AI inference, moving it from the server farm to the desktop.
Read the original at huggingface.co
Satirical commentary on real tech news, summarised with AI. Read the original source for the facts. How ZeroDaily works